
Logistic Regression Explained for Beginners
 Oct 23, 2026Published
10 min readReading time
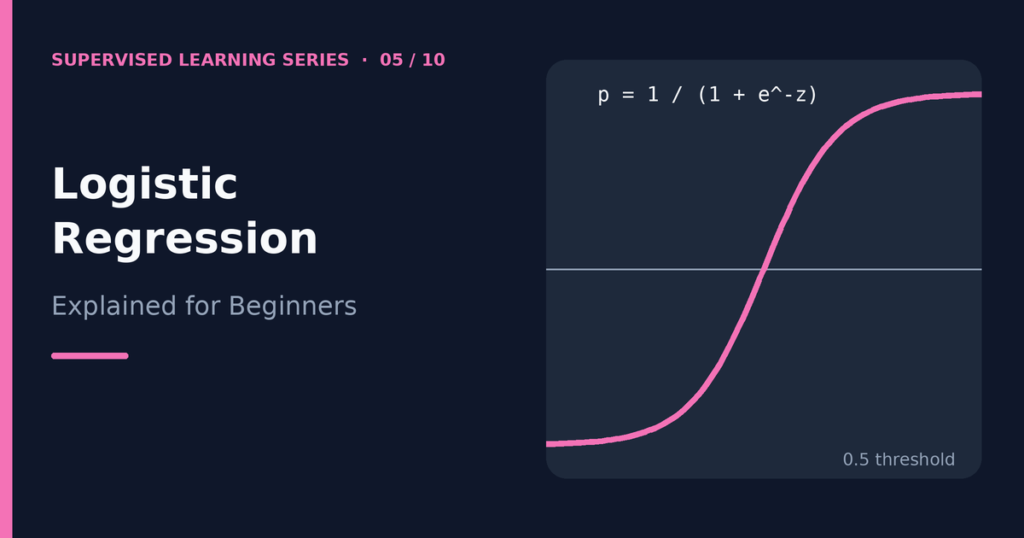
Logistic regression is a supervised learning algorithm that predicts the probability that an example belongs to a class, and then turns that probability into a class label. Despite its name, it is a classification method, not a regression method for predicting prices or temperatures. It answers questions such as “Is this email spam?” or “Will this customer cancel?” with a probability between 0 and 1.
This guide explains logistic regression for beginners. You will learn how it uses the sigmoid function, what decision thresholds do, how to read coefficients, how the loss function works, and how regularization and multiclass problems fit in. A complete Python example follows. If you need a refresher on the task type, see Classification vs Regression in Machine Learning.
Table of contents
- Why linear regression fails at classification
- The sigmoid function
- Probabilities and decision thresholds
- Reading the coefficients
- The loss function: log loss
- Multiclass classification
- Regularization
- Evaluation metrics
- Working Python example
- Strengths and limitations
- Frequently asked questions
- Conclusion
Why linear regression fails at classification
Imagine you code “passed” as 1 and “failed” as 0, then fit a straight line with linear regression. The line can output values like 1.4 or −0.3, which make no sense as probabilities. Outliers also tilt the line badly, so the predictions become unreliable near the boundary between the classes.
Logistic regression solves the problem with a clever step. It keeps the familiar linear equation but passes its result through a function that squeezes any number into the range between 0 and 1. The squeezed number works as a probability.
The sigmoid function
The model first computes a weighted sum of the features, exactly as linear regression does. We call this value z:
z = β₀ + β₁x₁ + β₂x₂ + … + βₚxₚ
Then the sigmoid function (also called the logistic function) converts z into a probability p:
p = 1 / (1 + e−z)
In this formula, e is the mathematical constant 2.718…, and p is the predicted probability of the positive class. The curve has an S shape. Large positive values of z give a probability near 1. Large negative values give a probability near 0. A z of exactly 0 gives 0.5.
| z | Sigmoid(z) = probability |
|---|---|
| −4 | 0.018 |
| −2 | 0.119 |
| 0 | 0.500 |
| 2 | 0.881 |
| 4 | 0.982 |
The sigmoid never reaches exactly 0 or 1. That behavior is useful, because the model always expresses at least a little uncertainty.
Probabilities and decision thresholds
A probability alone does not give you a class. You choose a decision threshold. The common default is 0.5: if p is at least 0.5, the model predicts the positive class, and otherwise it predicts the negative class.
The default is not always the best choice. Suppose a model screens for a serious illness, and missing a sick patient is worse than ordering an extra test. You might lower the threshold to 0.3 so that the model flags more cases. You trade more false alarms for fewer misses. In the opposite situation, such as blocking a legitimate payment, you might raise the threshold.
The threshold is a business or safety decision, not a property of the algorithm. Changing it does not retrain the model. It changes only how you convert probabilities into labels. The article on how to evaluate a supervised learning model shows how thresholds change precision and recall.
Reading the coefficients
Each coefficient β tells you how its feature moves z. A positive coefficient pushes the probability of the positive class up, and a negative coefficient pushes it down. A larger absolute value means a stronger push, provided that the features are on comparable scales.
For a deeper reading, use odds. The odds of an event are p divided by (1 − p). For example, a probability of 0.8 equals odds of 4 to 1. Logistic regression is linear in the log-odds:
log( p / (1 − p) ) = β₀ + β₁x₁ + … + βₚxₚ
This means that raising x₁ by one unit adds β₁ to the log-odds, or multiplies the odds by eβ₁. If β₁ equals 0.7, the odds multiply by about 2.0 for each one-unit increase, with the other features held constant. Notice that the effect on the probability itself is not constant. It depends on where you start on the S-curve.
As with linear regression, a coefficient describes an association in the data. It does not prove that the feature causes the outcome.
The loss function: log loss
Linear regression minimizes squared errors. Logistic regression uses a different loss, called log loss or binary cross-entropy, because squared error on sigmoid outputs creates a bumpy loss surface that is hard to optimize. For one example with true label y (0 or 1) and predicted probability p, the loss is:
loss = −[ y × log(p) + (1 − y) × log(1 − p) ]
This formula has an intuitive meaning. If the true label is 1, the loss is −log(p). A confident correct prediction (p near 1) gives a loss near 0. A confident wrong prediction (p near 0) gives a very large loss. The model therefore learns to be right, and it learns to avoid being confidently wrong. The training process averages this loss over all training examples and uses an optimizer, a relative of the gradient descent idea, to find the coefficients that minimize it.
Multiclass classification
Standard logistic regression handles two classes. Real problems often have more, such as three wine varieties or ten digits. Two main strategies extend the model:
- One-vs-rest (OvR). The method trains one binary model per class, each separating that class from all the others. For a new example, it picks the class whose model gives the highest probability.
- Multinomial (softmax) regression. The method learns all the classes together. A function called softmax converts one score per class into probabilities that add up to 1.
Scikit-learn’s LogisticRegression handles multiclass targets automatically, and its default solver uses the multinomial approach. You do not need to write any extra code.
Regularization
When a model has many features, or when the classes are perfectly separable, coefficients can grow very large and the model can overfit. Regularization adds a penalty for large coefficients, which keeps the model simpler. Two common penalties exist. The L2 penalty shrinks all coefficients smoothly, and the L1 penalty can shrink some coefficients all the way to zero, which acts as automatic feature selection.
In scikit-learn, the parameter C controls the strength, and it works in the opposite direction from what many beginners expect. C is the inverse of the regularization strength. A smaller C means stronger regularization. The default is C=1.0, and the default setting applies L2 regularization. You normally choose C with cross-validation. To learn why regularization helps, read Overfitting vs Underfitting in Machine Learning.
Because regularization penalizes coefficient size, you should scale your features first. Otherwise, a feature measured in large units gets treated differently from one measured in small units.
Evaluation metrics
Use classification metrics for logistic regression. Accuracy gives the overall share of correct predictions. Precision and recall describe the model’s performance on the positive class. F1-score combines the two. ROC-AUC measures how well the predicted probabilities rank positives above negatives, regardless of the threshold. Log loss itself is also a useful score, because it evaluates the probabilities directly.
When classes are imbalanced, accuracy alone can mislead you. Look at precision, recall, and a confusion matrix as well.
Working Python example
The example below uses the breast cancer dataset that ships with scikit-learn. It contains 569 tumor samples with 30 measurements each. In this dataset, class 0 means malignant and class 1 means benign, so the “positive” class that the probabilities describe is benign. The code scales the features inside a pipeline so that scaling is learned from the training data only.
from sklearn.datasets import load_breast_cancer
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import accuracy_score, classification_report, roc_auc_score

data = load_breast_cancer()
X_train, X_test, y_train, y_test = train_test_split(
    data.data, data.target, test_size=0.2, stratify=data.target, random_state=42)

model = make_pipeline(StandardScaler(), LogisticRegression(max_iter=1000))
model.fit(X_train, y_train)

proba = model.predict_proba(X_test)[:, 1]   # probability of class 1 (benign)
pred = (proba >= 0.5).astype(int)           # apply the 0.5 threshold ourselves
print("Accuracy:", round(accuracy_score(y_test, pred), 3))
print("ROC-AUC:", round(roc_auc_score(y_test, proba), 3))
print(classification_report(y_test, pred, target_names=data.target_names))
print("First 3 probabilities of class 'benign':", proba[:3].round(3))
The only required package is scikit-learn. When I ran this code with Python 3.12 and scikit-learn 1.8.0, it printed:
Accuracy: 0.982
ROC-AUC: 0.995
              precision    recall  f1-score   support

   malignant       0.98      0.98      0.98        42
      benign       0.99      0.99      0.99        72

    accuracy                           0.98       114
   macro avg       0.98      0.98      0.98       114
weighted avg       0.98      0.98      0.98       114

First 3 probabilities of class 'benign': [0.    1.    0.006]
The model classified about 98% of the 114 test samples correctly, and its ROC-AUC of 0.995 shows that its probabilities rank the two classes very well. The first three test samples receive probabilities near 0, near 1, and near 0.006, which means the model is very confident about them. This dataset is clean and easy, so do not expect such high scores on messy real-world data. Also remember that this is a learning exercise and not a medical tool.
Notice that max_iter=1000 gives the optimizer enough steps to converge. If you see a convergence warning in your own project, scaling the features or raising max_iter usually helps.
Strengths and limitations
Strengths
- It trains quickly, even on large datasets.
- It outputs probabilities, not only labels.
- Its coefficients are easy to interpret.
- It makes a strong, simple baseline for classification tasks.
Limitations
- It draws a linear decision boundary. It cannot capture complex curved patterns unless you add feature transformations.
- It is sensitive to outliers and to features on very different scales.
- It struggles when many features are highly correlated, unless you use regularization.
- Its probabilities can be poorly calibrated in some situations, so check them before relying on the exact values.
When the data has strong non-linear patterns, consider a tree-based model, such as those in Decision Trees in Machine Learning.
Frequently asked questions
Why is logistic regression called regression if it classifies?
The model uses a regression-style equation to compute z, and it estimates a continuous quantity, the probability. The name reflects those mathematical roots. The final job, choosing a class, makes it a classification algorithm.
What does the sigmoid function do in logistic regression?
The sigmoid converts the linear score z, which can be any real number, into a value between 0 and 1. That value is the predicted probability of the positive class.
What threshold should I use?
Start with 0.5, then adjust it according to the cost of each type of error. Use a validation set or cross-validation to choose a value, and do not tune it on the final test set.
Can logistic regression handle more than two classes?
Yes. Scikit-learn supports multiclass problems directly through multinomial (softmax) or one-vs-rest strategies.
Do I need to scale features for logistic regression?
Scaling is strongly recommended, especially with regularization or when the optimizer struggles to converge. A pipeline with StandardScaler makes this safe and simple.
Is logistic regression good enough for real projects?
Often, yes. Many production systems use it because it is fast, stable, and explainable. Compare it with other models on your own data, and let validation results guide the decision.
Conclusion
Logistic regression combines a linear equation with the sigmoid function to produce class probabilities. A decision threshold converts the probabilities into predictions, log loss trains the model, and regularization keeps it from overfitting. Its coefficients are easy to interpret, and it works well as a first model for classification problems.
Next, explore a model that makes decisions in a very different way. Decision Trees in Machine Learning: How They Work shows how a series of simple questions can split data into classes.
This article is for educational and informational purposes only. Examples and code are provided to help readers understand logistic regression and may require adaptation for specific projects. The medical dataset is used only to demonstrate a technique and is not a diagnostic tool.
Related guides
Compare this classifier with linear regression, then learn how to measure its performance in How to Evaluate a Supervised Learning Model.
References and further reading
- Linear Models: Logistic regression (scikit-learn user guide) for the loss function, regularization, and multiclass handling.
- Toy datasets (scikit-learn) for details of the breast cancer dataset.