
Ford-Fulkerson Algorithm: Interactive Visualization, Code & Complexity
Learn the Ford-Fulkerson algorithm with a live max-flow visualizer, step-by-step examples, Python, C++ and Java code, complexity analysis, and real uses.
 Oct 31, 2026Published
18 min readReading time
The Ford-Fulkerson algorithm finds the maximum flow in a network. It answers a simple question: how much water, traffic, or data can you push from a start point to an end point before the pipes, roads, or cables fill up? Lester Ford Jr. and Delbert Fulkerson published the idea in 1956, and it still sits at the heart of network flow theory today.
In this guide, you will learn how the algorithm works, watch it run in a live visualizer, load your own graph, and read working code in Python, C++ and Java. You will also see its time and space complexity, best, average and worst cases, how it compares with Edmonds-Karp and Dinic’s algorithm, and where people use it in the real world.
Interactive Visualization with Custom Input
Use the tool below to watch the algorithm work. Press Play to run it automatically, Pause to stop, Step Forward to move one action at a time, and Reset to start over.
- Orange edges are on the current augmenting path.
- Dashed red edges mean the path pushes flow backward through a reverse edge.
- Teal edges are full. Blue edges carry some flow.
- Each label shows
flow/capacity.
Custom input: type one edge per line as from to capacity, for example S A 16. Use whole numbers only. Set your source and sink names, choose DFS or BFS, then click Load graph.
Tip: Load the “Job matching” example and run it with DFS. Watch for the dashed red edge. The algorithm first gives worker B a job that worker A needs, then pushes that flow back along a reverse edge so both workers get a job. That single move shows why reverse edges matter.
Also, switch between DFS and BFS on the same graph. The final flow never changes, but the number of paths and scanned edges often does.
Key Takeaways
- The algorithm repeats one move: find a path with spare capacity, then push flow along it.
- Reverse edges in the residual graph let the algorithm undo earlier choices.
- With integer capacities, the running time is O(E × f), where f is the maximum flow value.
- With irrational capacities, it may never stop.
- Choosing paths with BFS turns it into the Edmonds-Karp algorithm, which runs in O(V × E²).
Table of Contents
- Interactive Visualization with Custom Input
- What Is the Ford-Fulkerson Algorithm?
- Key Concepts You Need First
- How the Algorithm Works, Step by Step
- Worked Example
- Algorithm Execution Statistics
- Python, C++ and Java Implementations
- Time and Space Complexity
- Best, Average and Worst Case Analysis
- Interactive Complexity Graph
- Ford-Fulkerson vs Related Algorithms
- Real-World Applications
- Common Mistakes
- Frequently Asked Questions
What Is the Ford-Fulkerson Algorithm?
The Ford-Fulkerson algorithm solves the maximum flow problem. You give it a directed graph where every edge has a capacity. You also name one node as the source and one as the sink. The algorithm then finds the largest amount of flow that can travel from the source to the sink without breaking any capacity limit.
Many authors call it a method instead of an algorithm. The reason is simple: it does not say how to find each path. You can pick paths with depth-first search (DFS), breadth-first search (BFS), or any other rule. Each choice gives you a different running time. When you use BFS, the result has its own name: the Edmonds-Karp algorithm.
People also search for this topic as “Ford Fulkerson,” “Fulkerson Ford,” or “Ford and Fulkerson algorithm.” All of these names point to the same idea.
Key Concepts You Need First
Five ideas make the whole algorithm easy to read. Learn them once, and the steps feel natural.
Flow network
A flow network is a directed graph with a source node, a sink node, and a capacity on each edge. Think of a system of pipes. Each pipe has a limit, and water enters at the source and leaves at the sink.
Flow and the three rules
A flow assigns a number to every edge. A valid flow follows these rules:
- Capacity rule: flow on an edge never exceeds its capacity.
- Conservation rule: for every node except the source and sink, flow in equals flow out.
- Skew symmetry: sending 3 units from u to v counts as sending −3 units from v to u.
Residual graph
The residual graph shows how much more flow each edge can still carry. For an edge u→v with capacity c and current flow f, the residual graph holds two edges:
- A forward edge u→v with residual capacity c − f (the room left).
- A backward edge v→u with residual capacity f (the flow you can cancel).
Augmenting path
An augmenting path is any path from the source to the sink in the residual graph where every edge has capacity above zero. If such a path exists, you can send more flow. If no such path exists, you have reached the maximum.
Bottleneck capacity
The bottleneck is the smallest residual capacity along the chosen path. It sets how much flow you can push in one round.
How the Algorithm Works, Step by Step
Here is the full process in plain language:
- Start with zero flow on every edge. The residual graph equals the original graph.
- Search for an augmenting path from the source to the sink in the residual graph. Use DFS or BFS.
- Find the bottleneck. Take the minimum residual capacity along the path.
- Augment the flow. For each edge on the path, add the bottleneck to the forward flow. If the path used a backward edge, subtract the bottleneck from the original edge’s flow.
- Update the total flow by adding the bottleneck.
- Repeat from step 2 until no augmenting path exists.
- Return the total. That number is the maximum flow.
Pseudocode
FORD-FULKERSON(G, s, t)
    for each edge (u, v) in G:
        flow(u, v) = 0

    while there is a path p from s to t in the residual graph:
        bottleneck = min residual capacity on p
        for each edge (u, v) on p:
            if (u, v) is a forward edge:
                flow(u, v) = flow(u, v) + bottleneck
            else:
                flow(v, u) = flow(v, u) - bottleneck

    return the sum of flow leaving s
Why the answer is correct
The proof rests on the max-flow min-cut theorem. When the algorithm stops, the source cannot reach the sink in the residual graph. Let S be the set of nodes the source can still reach. Every edge leaving S is full, and every edge entering S carries zero flow. So the flow you found equals the capacity of the cut between S and the rest of the graph. No flow can beat the capacity of any cut, so your flow is the maximum. The same argument gives you the minimum cut for free.
Worked Example
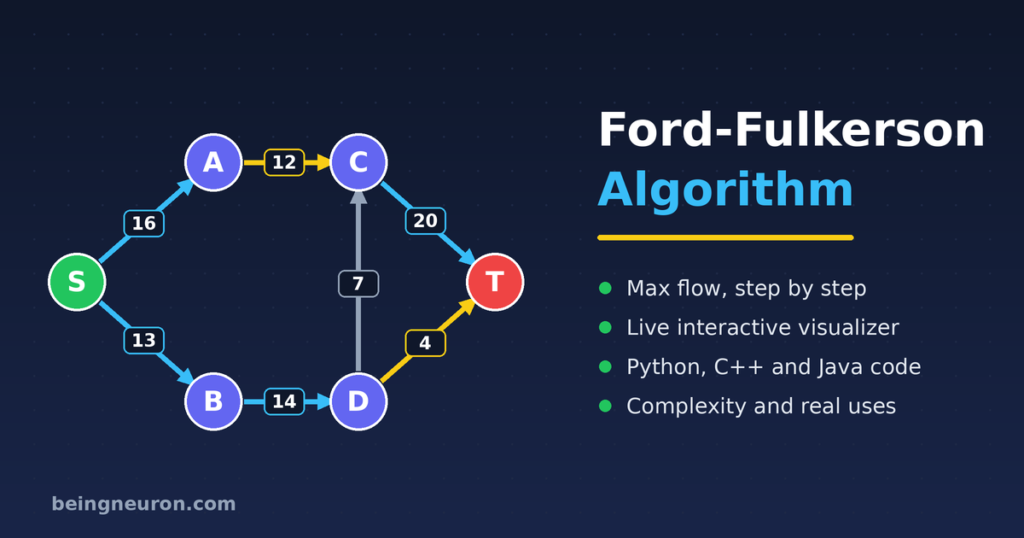
Take the textbook network below. It has six nodes: S (source), A, B, C, D, and T (sink). The capacities appear on the edges.
Here is one run using DFS:
- Path S → A → C → T. The bottleneck is 12 (edge A→C). Total flow: 12.
- Path S → B → D → T. The bottleneck is 4 (edge D→T). Total flow: 16.
- Path S → B → D → C → T. Edge S→B has 13 − 4 = 9 left, B→D has 14 − 4 = 10 left, D→C has 7, and C→T has 20 − 12 = 8 left. The bottleneck is 7. Total flow: 23.
- Now S→A still has 4 left, but A→C is full and A→B leads only to B, whose exits are blocked. S→B has 2 left, but B→D has 3 left and D’s exits (D→C and D→T) are full. No augmenting path remains.
The maximum flow is 23. Different path choices give different step counts, but the final answer never changes. Try it yourself in the visualizer below.
Algorithm Execution Statistics
The panel under the visualizer tracks the run as it happens. Here is what each number tells you:
| Statistic | What it shows |
|---|---|
| Step | Your position in the full run. Each augmentation takes two steps: find the path, then push the flow. |
| Augmenting paths | How many paths the algorithm used. This is the number that drives the O(E × f) bound. |
| Current flow | The total flow sent from source to sink so far. |
| Edges scanned | How many residual edges the search looked at. It is a practical stand-in for work done. |
| Nodes / edges | The size of your graph (V and E in the formulas). |
| Compute time | How long your browser took to precompute the run. For tiny graphs, it is close to zero. |
Use these numbers to run small experiments. Build a graph with large capacities and a thin “bridge” edge in the middle. Then compare DFS and BFS. You will often see DFS take many more paths than BFS on such graphs.
Python, C++ and Java Implementations
All three versions below use the same plan. They store the graph as an adjacency matrix, copy it into a residual matrix, and find each augmenting path with a recursive DFS. Each DFS returns the flow it managed to push. The main loop adds that flow to the total and stops when the DFS returns zero. All three print Maximum flow: 23 for the textbook graph above, with nodes numbered S=0, A=1, B=2, C=3, D=4, T=5. I ran the Python and C++ versions to confirm that output.
Python
def ford_fulkerson(capacity, source, sink):
    n = len(capacity)
    residual = [row[:] for row in capacity]  # copy so the input stays unchanged

    def dfs(u, flow, visited):
        if u == sink:
            return flow
        visited[u] = True
        for v in range(n):
            if not visited[v] and residual[u][v] > 0:
                pushed = dfs(v, min(flow, residual[u][v]), visited)
                if pushed > 0:
                    residual[u][v] -= pushed   # use forward capacity
                    residual[v][u] += pushed   # add reverse capacity
                    return pushed
        return 0

    max_flow = 0
    while True:
        pushed = dfs(source, float("inf"), [False] * n)
        if pushed == 0:
            break
        max_flow += pushed
    return max_flow


graph = [
    [0, 16, 13, 0, 0, 0],
    [0, 0, 10, 12, 0, 0],
    [0, 4, 0, 0, 14, 0],
    [0, 0, 9, 0, 0, 20],
    [0, 0, 0, 7, 0, 4],
    [0, 0, 0, 0, 0, 0],
]
print("Maximum flow:", ford_fulkerson(graph, 0, 5))
C++
#include <iostream>
#include <vector>
#include <algorithm>
#include <climits>
using namespace std;

int dfs(vector<vector<int>>& residual, int u, int sink, int flow, vector<bool>& visited) {
    if (u == sink) return flow;
    visited[u] = true;
    for (int v = 0; v < (int)residual.size(); v++) {
        if (!visited[v] && residual[u][v] > 0) {
            int pushed = dfs(residual, v, sink, min(flow, residual[u][v]), visited);
            if (pushed > 0) {
                residual[u][v] -= pushed;  // use forward capacity
                residual[v][u] += pushed;  // add reverse capacity
                return pushed;
            }
        }
    }
    return 0;
}

int fordFulkerson(vector<vector<int>> residual, int source, int sink) {
    int maxFlow = 0;
    while (true) {
        vector<bool> visited(residual.size(), false);
        int pushed = dfs(residual, source, sink, INT_MAX, visited);
        if (pushed == 0) break;
        maxFlow += pushed;
    }
    return maxFlow;
}

int main() {
    vector<vector<int>> graph = {
        {0, 16, 13, 0, 0, 0},
        {0, 0, 10, 12, 0, 0},
        {0, 4, 0, 0, 14, 0},
        {0, 0, 9, 0, 0, 20},
        {0, 0, 0, 7, 0, 4},
        {0, 0, 0, 0, 0, 0}
    };
    cout << "Maximum flow: " << fordFulkerson(graph, 0, 5) << endl;
    return 0;
}
Java
public class FordFulkerson {

    static int dfs(int[][] residual, int u, int sink, int flow, boolean[] visited) {
        if (u == sink) return flow;
        visited[u] = true;
        for (int v = 0; v < residual.length; v++) {
            if (!visited[v] && residual[u][v] > 0) {
                int pushed = dfs(residual, v, sink, Math.min(flow, residual[u][v]), visited);
                if (pushed > 0) {
                    residual[u][v] -= pushed;  // use forward capacity
                    residual[v][u] += pushed;  // add reverse capacity
                    return pushed;
                }
            }
        }
        return 0;
    }

    static int fordFulkerson(int[][] graph, int source, int sink) {
        int n = graph.length;
        int[][] residual = new int[n][];
        for (int i = 0; i < n; i++) residual[i] = graph[i].clone();

        int maxFlow = 0;
        while (true) {
            int pushed = dfs(residual, source, sink, Integer.MAX_VALUE, new boolean[n]);
            if (pushed == 0) break;
            maxFlow += pushed;
        }
        return maxFlow;
    }

    public static void main(String[] args) {
        int[][] graph = {
            {0, 16, 13, 0, 0, 0},
            {0, 0, 10, 12, 0, 0},
            {0, 4, 0, 0, 14, 0},
            {0, 0, 9, 0, 0, 20},
            {0, 0, 0, 7, 0, 4},
            {0, 0, 0, 0, 0, 0}
        };
        System.out.println("Maximum flow: " + fordFulkerson(graph, 0, 5));
    }
}
Turn it into Edmonds-Karp
To switch to Edmonds-Karp, replace the recursive DFS with a BFS that stores each node’s parent. Then walk back from the sink to the source, find the bottleneck, and update the residual matrix. Nothing else changes. That small swap gives you a guaranteed polynomial running time.
Time and Space Complexity
Time complexity
With integer capacities, the Ford-Fulkerson algorithm runs in O(E × f) time. Here E is the number of edges and f is the value of the maximum flow. The logic is short:
- Each augmentation pushes at least 1 unit of flow, so there are at most f augmentations.
- Each DFS or BFS on an adjacency list takes O(V + E) time, which is O(E) for a connected graph.
- Multiply the two: O(E × f).
The adjacency-matrix code above scans a whole row for every node it visits, so each search costs O(V²). Its total time is O(V² × f). Switch to adjacency lists if you want the O(E × f) bound.
Is Ford-Fulkerson polynomial time?
No. The bound depends on the flow value, not on the input size. A capacity of 1,000,000 takes about 20 bits to write, but it can cause up to a million augmentations. Computer scientists call this pseudo-polynomial time. Edmonds-Karp fixes it. Its O(V × E²) bound depends only on the graph’s shape.
Space complexity
- Adjacency matrix: O(V²) to store capacities and the residual graph.
- Adjacency list: O(V + E), because each edge stores its reverse partner.
- Search overhead: O(V) for the visited array and the recursion stack or BFS queue.
When it does not terminate
If capacities are irrational numbers, a bad path choice can keep adding smaller and smaller flows forever. The total may even converge to a value below the true maximum. Real programs use integers or rational numbers, so this problem stays mostly theoretical. Still, it is a strong reason to prefer BFS-based Edmonds-Karp, which always stops.
A useful side effect: integral flows
When all capacities are integers, every augmentation adds an integer. So the final flow on each edge is also an integer. This integrality theorem is why the algorithm solves matching problems so well.
Best, Average and Worst Case Analysis
| Case | When it happens | Time |
|---|---|---|
| Best case | One augmenting path saturates everything, or the sink is unreachable from the start. The algorithm needs one or two searches. | O(E) |
| Average case | Typical graphs need far fewer augmentations than f, but no clean formula exists. It depends on the graph and on the path-search order. | Between O(E) and O(E × f); often close to a small multiple of O(E) |
| Worst case | Every augmentation pushes only 1 unit, so the algorithm needs f of them. A thin bridge edge between two large parts causes this when paths are chosen badly. | O(E × f) |
The classic worst case uses four nodes. The source feeds two nodes with huge capacities, and a middle edge with capacity 1 links them. An unlucky search keeps routing one unit through the middle edge, then pushing it back, and so on. With capacities of 1,000, that takes 2,000 rounds for a graph with five edges. Choosing the shortest path (BFS) finishes it in two rounds. Note that this behavior needs an adversarial choice of paths. A plain DFS with a fixed neighbor order often avoids it, which is why you should not expect to trigger it by accident in the visualizer.
Why is the average case hard to state? Because “average” needs a probability model for graphs, and flow networks come from so many different sources. In practice, programmers measure real inputs instead.
Interactive Complexity Graph
The chart below compares the worst-case bounds of three max-flow algorithms. Move the sliders to change the graph size and the maximum flow value. The vertical axis uses a log scale, so each gridline is ten times higher than the one below it.
The orange line grows with f, because Ford-Fulkerson pays for every unit of flow. The other two lines stay flat, because their bounds do not depend on f. The gray dashed line marks where f equals V × E, the point at which the Ford-Fulkerson bound overtakes Edmonds-Karp. Remember that real running times are often far better than these bounds.
Ford-Fulkerson vs Related Algorithms
| Algorithm | How it picks paths | Worst-case time | Best for |
|---|---|---|---|
| Ford-Fulkerson | Any path (often DFS) | O(E × f) | Learning, small integer capacities |
| Edmonds-Karp | Shortest path by edge count (BFS) | O(V × E²) | Safe default, guaranteed to stop |
| Capacity scaling | Only paths with large residual capacity | O(E² log U), where U is the largest capacity | Graphs with very large capacities |
| Dinic's algorithm | Level graph plus blocking flows | O(V² × E) | Contests and large sparse graphs |
| Push-relabel | Pushes local "preflow" instead of whole paths | O(V² × E) generic; better with heuristics | Dense graphs, fast in practice |
Ford-Fulkerson vs Edmonds-Karp
Edmonds-Karp is Ford-Fulkerson with one rule: always take the augmenting path with the fewest edges. That rule guarantees at most O(V × E) augmentations, so the running time no longer depends on capacities. If you only remember one thing from this section, remember this: Edmonds-Karp is a specific, safer version of Ford-Fulkerson.
Ford-Fulkerson vs Dinic's algorithm
Dinic's algorithm builds a level graph with BFS and then sends a blocking flow through it with DFS. It finds many augmenting paths per BFS instead of one. This makes it much faster on large graphs, and it is the usual choice in programming contests.
Ford-Fulkerson vs push-relabel
Push-relabel works differently. It lets nodes hold extra flow temporarily and pushes that excess toward the sink along "downhill" edges. It never builds full source-to-sink paths. With good heuristics, it is among the fastest approaches on dense networks. Faster theoretical algorithms exist too. For example, Orlin's 2013 algorithm solves max flow in O(V × E) time, but it is rarely used in practice because of its complexity.
Is Ford-Fulkerson a greedy algorithm?
Most sources call it greedy, and that label is fair. At each step it grabs any available path and commits to it. The twist is that a normal greedy algorithm cannot undo its choices. Ford-Fulkerson can, because reverse edges let later paths cancel earlier flow. That ability is what makes it correct.
Real-World Applications
Max-flow ideas show up in many fields. Often, the trick is to model a problem as a flow network and let the algorithm do the rest.
- Bipartite matching: Assign workers to jobs, students to projects, or doctors to shifts. Give every edge capacity 1, add a source in front of one side and a sink behind the other, and the max flow equals the largest possible matching.
- Network routing and bandwidth: Find the most data a network can carry between two points, and spot the links that limit it. The minimum cut shows the weakest set of links.
- Transportation and supply chains: Move goods from factories to warehouses to stores through roads and rail lines that each have a capacity.
- Airline and crew scheduling: Model flights, planes, and crews as flow so the schedule covers all routes with the fewest resources.
- Image segmentation: Treat pixels as nodes and similarity as capacity. A minimum cut then separates foreground from background.
- Project selection: Choose a set of projects and the tools they need to maximize profit. This reduces to a minimum cut.
- Sports elimination: Decide whether a team can still finish first in a league. The baseball elimination problem is a classic flow application.
- Network reliability: Count how many edge-disjoint paths connect two points. That number tells you how many link failures the connection can survive.
- Water, gas, and power grids: Estimate how much a pipe or cable system can deliver, and where upgrades help most.
Two modeling tricks help you apply the algorithm to messier problems. First, if you have several sources or sinks, add one "super source" and one "super sink" joined by edges of infinite capacity. Second, if a node itself has a capacity limit, split it into an "in" node and an "out" node joined by an edge with that capacity.
Common Mistakes
- Forgetting reverse edges. Without them, the code can stop early and report a flow below the true maximum.
- Not copying the graph. The algorithm changes capacities as it runs. Copy the matrix if you need the original later.
- Using floating-point capacities. Rounding errors can cause tiny, endless augmentations. Use integers when you can.
- Mixing up the bottleneck. Use the minimum residual capacity on the path, not the minimum original capacity.
- Not resetting the visited array. Create a fresh visited array for every search.
- Ignoring recursion depth. A recursive DFS on a long path can overflow the stack. Use an iterative search for very large graphs.
Frequently Asked Questions
What is an augmenting path in the Ford-Fulkerson algorithm?
It is a path from the source to the sink in the residual graph, where every edge still has capacity above zero. Sending flow along it increases the total flow.
How does Ford-Fulkerson work?
It starts with zero flow, finds an augmenting path, pushes the bottleneck amount along it, updates the residual graph, and repeats. When no path remains, the total flow is the maximum.
How do you find an augmenting path in the Ford-Fulkerson method?
Run DFS or BFS from the source over residual edges that have capacity above zero. Stop when you reach the sink. Store each node's parent so you can rebuild the path.
Is Ford-Fulkerson polynomial time?
No. It is pseudo-polynomial, because its O(E × f) bound grows with the flow value. Edmonds-Karp makes it polynomial by choosing shortest paths.
Is Ford-Fulkerson a greedy algorithm?
Yes, in the sense that it takes any available path at each step. Reverse edges let it undo earlier choices, which keeps it correct.
Does it work on undirected graphs?
Yes. Replace each undirected edge with two directed edges, one in each direction, and give both the original capacity.
Why is it called a method instead of an algorithm?
Because it leaves the path-finding rule open. Each rule produces a different algorithm with its own running time.
Conclusion
The Ford-Fulkerson algorithm teaches a big idea in a small package: keep improving a solution until no improvement is left, and keep an "undo" option available. You now know the key terms, the step-by-step process, working code in three languages, and how the running time depends on the maximum flow. You have also seen how it compares with Edmonds-Karp, Dinic's algorithm, and push-relabel.
Go back to the visualizer and try your own graph. Change a capacity, switch from DFS to BFS, and watch the statistics change. Hands-on practice is the fastest way to make the idea stick.
Sources and Further Reading
- L. R. Ford Jr. and D. R. Fulkerson, "Maximal Flow Through a Network," Canadian Journal of Mathematics, 1956.
- Cormen, Leiserson, Rivest and Stein, Introduction to Algorithms, chapter on maximum flow.
- Wikipedia: Ford–Fulkerson algorithm; Edmonds–Karp algorithm; Max-flow min-cut theorem.
- Tutorials on the topic by GeeksforGeeks, Programiz, W3Schools and Brilliant, reviewed to choose the topics covered here.